Running your own model doesn’t solve every problem with LLMs, but it sure as hell does solve a ton of them, for way less money! Local models are great, gwen3.8 on my 3090 at home is slower, but often better than the pay to play Claude from work.
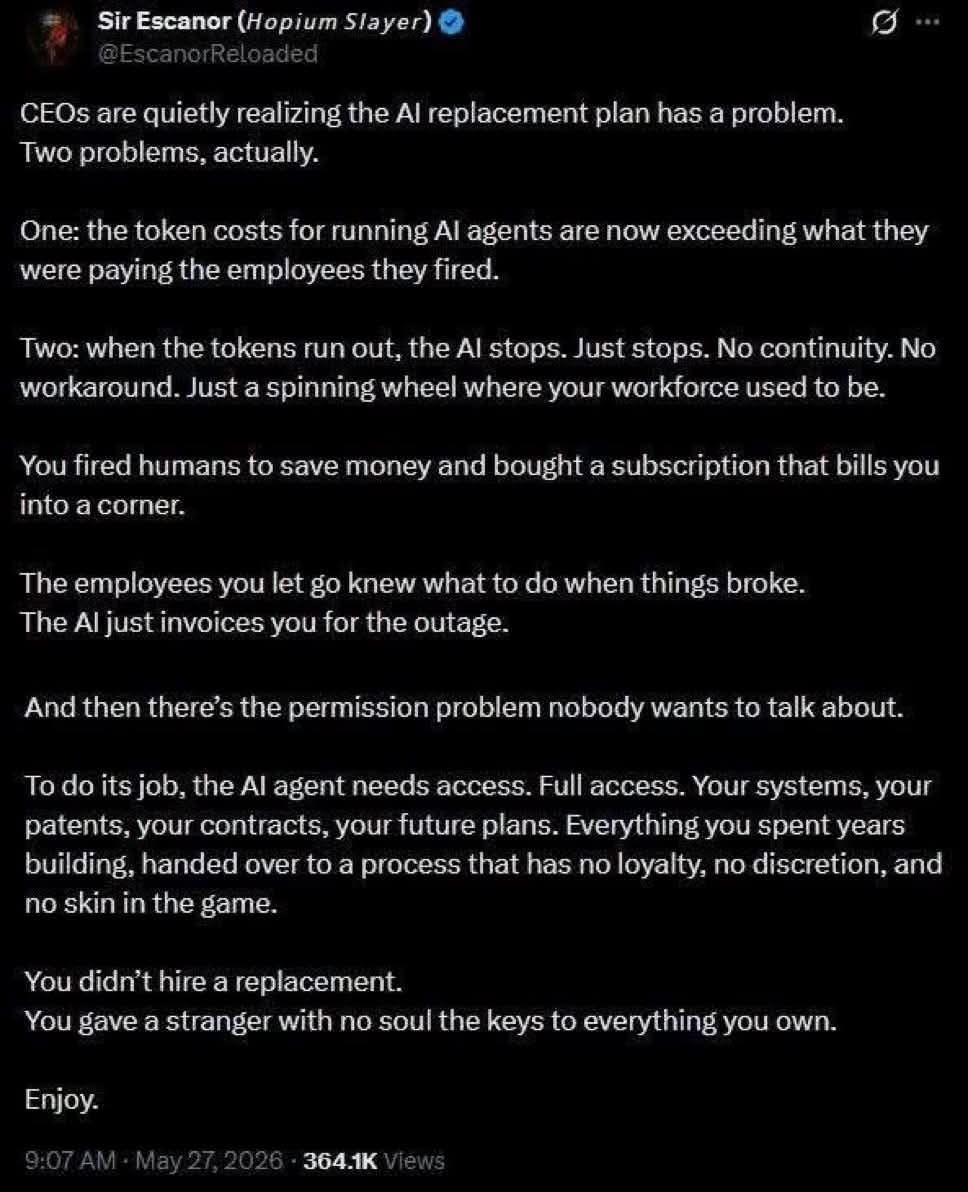
It maybe doesn’t solve ALL problems, but it solves the ones in this post: high token prices, running out of tokens shutting down the workflow, and handing over your sensitive data to corporates doing god knows what with it.
One of the better aspects of it is that it decentralizes power and cooling. When everyone has to juice up their own GPU and deal with the noise it makes in their office, you remove a lot of the problems related to the data center chewing up enormous amounts of electricity and water (or rather, if lots of people did that, it would target that problem). And that’s a lot more tolerable than giant data centers increasing the local temperature and chugging down the municipal water supply. Problem being that GPUs are now way too expensive. This will be a more approachable model when the bubble bursts (I hope).
That’s what I run on my 7900 XTX and it’s about as good as Sonnet 5 that I use regularly at work. Zero reason to give Anthropic or OpenAI my money or data.
I mean, not quite, but also yes.
Running your own model doesn’t solve every problem with LLMs, but it sure as hell does solve a ton of them, for way less money! Local models are great, gwen3.8 on my 3090 at home is slower, but often better than the pay to play Claude from work.
It maybe doesn’t solve ALL problems, but it solves the ones in this post: high token prices, running out of tokens shutting down the workflow, and handing over your sensitive data to corporates doing god knows what with it.
One of the better aspects of it is that it decentralizes power and cooling. When everyone has to juice up their own GPU and deal with the noise it makes in their office, you remove a lot of the problems related to the data center chewing up enormous amounts of electricity and water (or rather, if lots of people did that, it would target that problem). And that’s a lot more tolerable than giant data centers increasing the local temperature and chugging down the municipal water supply. Problem being that GPUs are now way too expensive. This will be a more approachable model when the bubble bursts (I hope).
Exactly, that’s why I gave it the “No, but actually yes” preface.
That’s what I run on my 7900 XTX and it’s about as good as Sonnet 5 that I use regularly at work. Zero reason to give Anthropic or OpenAI my money or data.